



Technology
Diffio Pitches AI Speech Restoration as a Cheap Middle Ground Between Phone Audio and the Studio

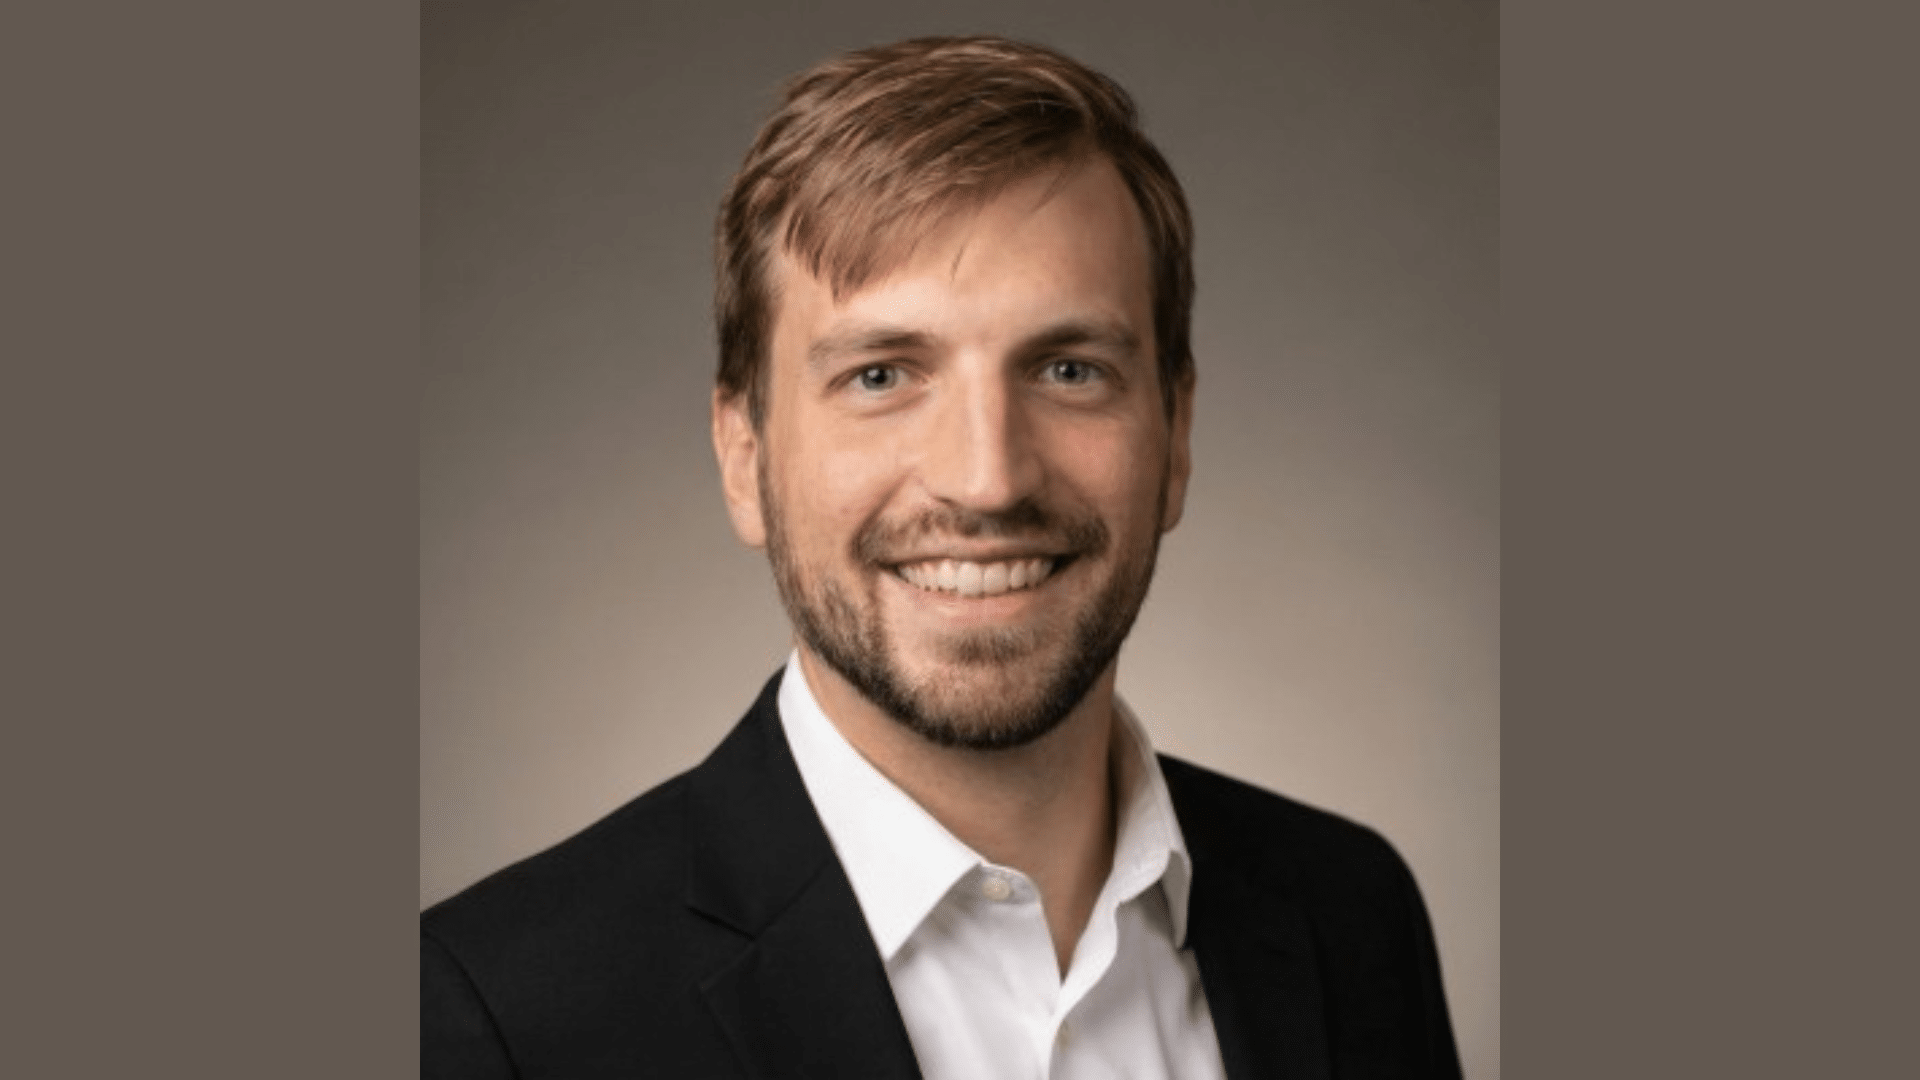
A podcast interview recorded on a phone in an echoing room can come back with words missing. Heavy background noise buries them, and echo stacks delayed copies of the same voice. Diffio, an AI speech restoration tool, is designed to rebuild that damaged speech from the rest of the recording, pitching itself as the affordable middle ground between a phone and a professional studio.
“Diffio probably doesn’t get you all the way there, but it gets you pretty close, and it’s very cheap,” says founder Nathan Harmon. “You can just use whatever equipment you’ve got, including your phone.” Creators who can afford an acoustically designed studio should build one, in Nathan’s view, though a studio limits where they record and some guests won’t travel to it.
Rebuilding speech from a phone recording draws on about a decade Nathan spent processing electromagnetic signals, much of it as a machine learning researcher at Northrop Grumman, and he turned those methods on audio after struggling through old sermons recorded on cheap equipment. He founded Diffio in Colorado Springs in 2025, under Ozni Apps, LLC, and runs it alone.
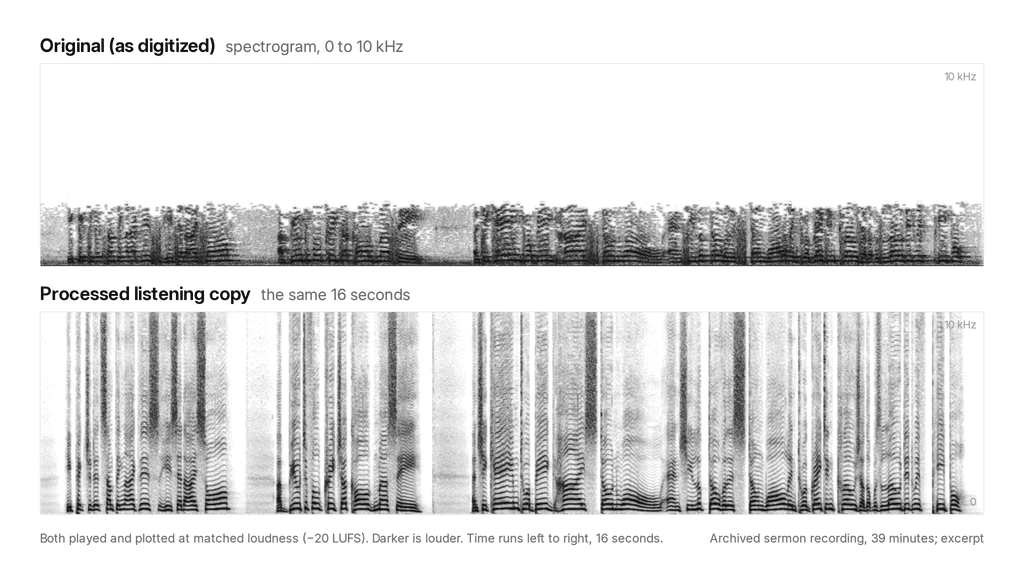
Sermons became an early use case. Small churches clean them up before posting; other customers have restored wedding videos shot on a guest’s phone, and one archivist keeps a restored copy beside each original. Nathan doesn’t yet know how far the product has reached into the Creator Economy, but he sees creators who are starting out as a fit, since they often can’t control where they record and good equipment is expensive early on.
Restoration Rebuilds Speech That Noise Removal Leaves Out
For those creators, Nathan separates Diffio from the noise removal built into most editing software. Standard removal strips static or clapping but usually leaves echo, which, according to Nathan, is harder to fix because the voice reaches the microphone several times. “The algorithm has to determine which of those was actually the primary source and then remove the other ones,” he explains.
Restoration also covers speech the noise has destroyed. “It’ll actually rebuild what they said based on the other areas of the audio that you can hear them speaking correctly in, and it’ll handle packet loss,” Nathan says.
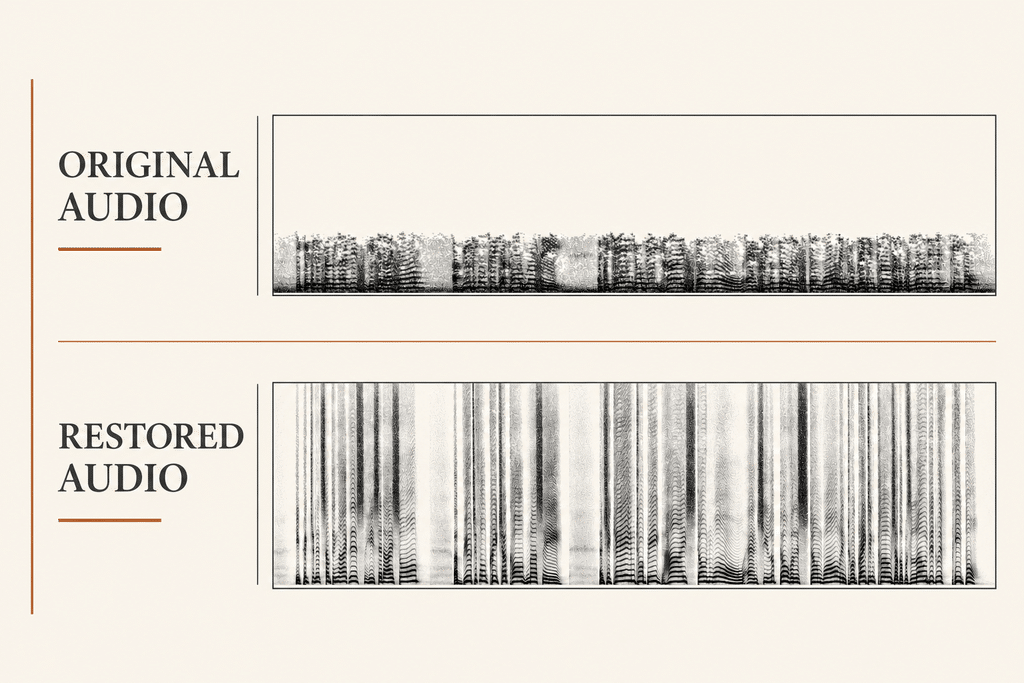
Diffio returns the restored speech plus a separate background track, which also holds any music, since Nathan argues it isn’t clear what reconstructing music would mean. Creators can mix some background back in, which he recommends for outdoor footage. “It’s very disconcerting to someone watching your video, because it’s like, ‘Well, I can see that there’s wind and I can’t hear any of it,’” he adds.
Rebuilt words are partly generated, though, and the share depends on how much of the original survived.
Heavily Damaged Audio Leaves the Model Guessing
That share scales with distortion, according to Nathan. Clean audio passes through unchanged. A long recording gives the model enough material to estimate what the speaker’s voice sounded like without the effects of a low-quality mic, crowd noise, and room echo. “It’s not an absolutely guaranteed accurate reconstruction, but it is a probabilistically correct reconstruction,” he says.
Dropped packets on a call usually last under a second, so Diffio can rebuild them with high confidence. The limit arrives when nothing in the recording reveals the speaker’s voice. “It probably will reconstruct some speech, but it’ll probably not sound like the speaker,” Nathan cautions.
Creators Should Check the Noisiest Passage Before Posting
That failure case is why Nathan recommends listening to every restored file. “Maybe there’s a really noisy part in the middle, and that’s actually going to be the hardest part to reconstruct,” he says. “You should go listen to that part.”
Language is the second check. English tolerates the most noise because Diffio has the most training data for it, followed by Spanish and Portuguese, in Nathan’s ranking, while Hindi works only on cleaner recordings. A Spanish-language clip that Net Influencer sent ahead of the interview failed on the current production model and came through on an internal model he says is close to release.
“If you do find failures, you can email us at support, and usually we’ll get back to you right away,” he notes. Diffio will try its internal models on those files and offer extra copies or free credits.
Sending recordings back also raises the question of what happens to uploads.
Uploaded Files Can Be Kept Out of Training
Diffio’s terms of service and privacy policy require users to opt in before their uploads can be used for model training, although Nathan says the company hasn’t done so. “For training, we need high-quality audio, and implicitly our users are uploading low-quality audio,” he explains. He says opting out shuts off training and metrics for the account, and deleted files are removed from all of Diffio’s servers with no recovery.
For sponsored or unreleased work, Nathan suggests uploading, downloading the result, and deleting it. Outputs carry no restrictions and can be used for any purpose, including benchmarking.
Diffio Claims Its Edge on Badly Distorted Audio
By Nathan’s count, Diffio has run real clips through about five competitors, including Adobe Podcast, ElevenLabs and Audacity, measuring predicted speech quality and word accuracy, since some tools change words or blur pronunciation. Diffio’s output still contains some errors, according to Nathan. “But out of all the solutions, it is the best on those metrics,” he adds.
Nathan doesn’t claim the lead everywhere. “In general, if your audio is not really distorted, you probably can get away with using anyone,” he says. ElevenLabs separates background noise without reconstructing speech, in his telling, while Adobe Podcast does both and adds a dedicated music track Diffio lacks. “That is something that Adobe Podcast currently does better than us,” he acknowledges.
At the time of the interview, Nathan said Diffio couldn’t publish its benchmarks because of competitors’ terms, so he suggested creators run free trials side by side. Diffio has since published comparative results involving 59 recordings. Its free trial covers three uploads, previewing the first two minutes of each, because running the model costs money.
Used Mac minis Let Diffio Charge $8 a Month
That running cost shaped Diffio’s pricing. GPUs were the largest expense, and in Nathan’s account, their prices kept climbing as major AI labs absorbed supply. “Every month, instead of our stuff getting cheaper, our costs were going up,” he says. Diffio shrank its model enough to run inference on used Mac minis it self-hosts in Colorado Springs, which are cheaper and more power-efficient than GPUs.
The switch lets Diffio charge its current prices at a margin, Nathan says. The “Basic” plan costs $8 a month for six hours of audio, and “Pro” costs $29 a month for 30 hours.
The same hardware limits the recently launched API, which has seen little use. Its demand is usage-based and spiky, unlike subscription revenue. “Somebody throws a thousand jobs at us and, because we’re hosting our own hardware, we cannot just scale our compute to absorb a giant job like that,” Nathan says.
The cost structure behind the $8 plan is what holds back the API. “Part of it is our choices to move towards as cheap a model as we can,” he explains. He also thinks the API is probably priced too high for large-scale adoption and calls the fix an engineering problem that hasn’t reached the front burner.
Diffio Wants Fewer Steps Between Recording and Publishing
On the front burner instead is a new model with better multilingual support, nearly ready at the time of the interview. Diffio currently returns a single reconstruction tuned to what groups of listeners enjoy, and Nathan hopes to let users supply a room environment for it to emulate.
His five-year view is broader. Nathan wants recording to publishing to take only a few steps at a computer, with edits set to a creator’s taste and distributed to platforms in their style. Diffio today handles one of those steps: speech that gets close to studio quality from cheap equipment, at a price set by used hardware, with the creator still listening for where the model guessed.
“That process is what stops me from creating content,” Nathan says. “It’s just so much work, so much time.”
Subscribe to Our Newsletter
Check Out Our Podcast